Blake Meier · 7 September 2026
Navigating Resource Allocation Challenges in Evolving Site Architectures
Site architectures continue to shift as organizations move from monolithic setups toward distributed systems that incorporate microservices, edge computing nodes, and dynamic content delivery networks, and these transitions create ongoing demands on how computing power, bandwidth, and storage get assigned at each stage. Researchers at various institutions have documented how early-stage planning often underestimates the scaling requirements that appear once traffic patterns change or new features roll out, because initial resource maps rarely account for the full range of interactions between components that only surface during live operation.
Core Pressures in Modern Infrastructure Planning
Teams managing these environments frequently encounter situations where sudden spikes in user activity coincide with backend service updates, and the resulting competition for CPU cycles or memory pools forces rapid rebalancing that can disrupt ongoing processes. Data from industry reports indicates that organizations handling multi-region deployments face additional layers of complexity, since latency requirements and data sovereignty rules vary by jurisdiction and therefore influence where processing resources must sit at any given moment.
Observers tracking these developments point out that legacy monitoring tools often fail to capture the granular usage metrics needed for accurate forecasting, which leaves planners relying on incomplete snapshots that miss inter-service dependencies. In September 2026, several standards bodies plan to release updated guidelines on telemetry collection that aim to address this gap by standardizing how resource consumption gets logged across hybrid cloud setups.
Approaches That Have Shown Consistent Results
One study revealed that implementing automated orchestration layers capable of reallocating containers based on real-time load signals reduced downtime incidents by measurable margins across tested environments, while another project demonstrated that predictive models trained on historical traffic data helped teams pre-provision storage before seasonal events triggered higher demand. Experts have noted that combining these automated systems with periodic manual reviews allows adjustments that pure algorithms sometimes overlook when unusual edge cases arise.
Organizations that adopted capacity buffers sized according to regional traffic variance rather than global averages reported steadier performance during localized surges, and similar patterns appeared in reports covering both North American and Asia-Pacific deployments. The National Institute of Standards and Technology has published frameworks that outline metrics for evaluating these buffers in enterprise contexts, providing reference points that planners can adapt to their specific traffic profiles.
Handling Dependencies Across Layers
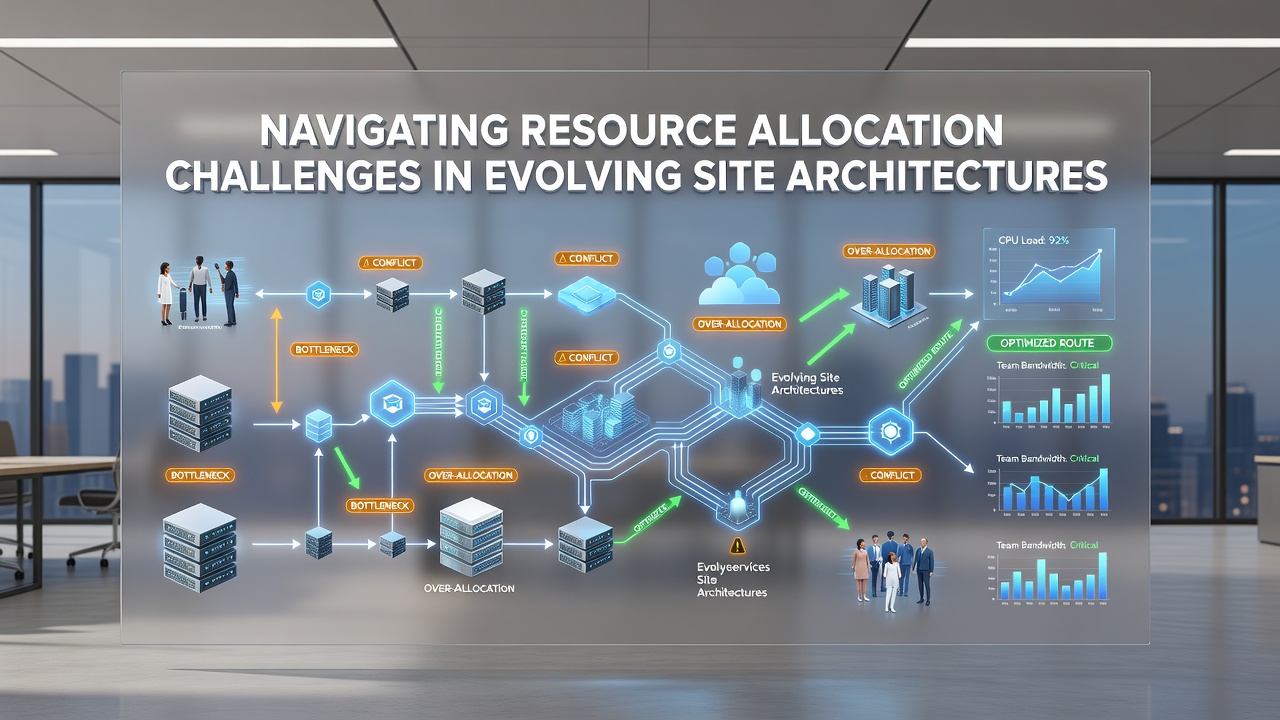
As architectures incorporate additional services such as AI inference endpoints or real-time personalization engines, the interdependencies between front-end rendering adn back-end data pipelines grow more intricate, and misaligned resource assignments at any single layer can cascade into broader slowdowns. Analysts tracking these interactions have found that mapping dependency graphs early in the design phase helps identify potential bottlenecks before they manifest under production loads.
Teams that integrated cross-layer visibility dashboards discovered they could correlate frontend request patterns with backend queue depths more effectively, which in turn supported quicker decisions about where to direct additional processing capacity during peak periods. Evidence from academic papers on distributed systems suggests that such visibility becomes especially valuable once the number of independent services exceeds a certain threshold, because manual tracking becomes impractical at that scale.
Regional Variations and Regulatory Influences
Regulatory requirements in different jurisdictions add another dimension, since data residency rules in the European Union and privacy standards in Canada affect where certain processing tasks can occur and therefore shape how resources get distributed across available zones. Government agencies in Australia have issued guidance documents that emphasize the need for contingency allocations when cross-border data flows encounter unexpected restrictions, and similar considerations appear in technical briefs from research consortia operating in multiple continents.
Planners who factor these constraints into their allocation models from the outset tend to experience fewer last-minute reconfigurations, according to summaries compiled by international standards organizations. The patterns observed across these regions show that early incorporation of compliance parameters into capacity planning reduces the frequency of reactive adjustments later in the deployment cycle.
Conclusion
Resource allocation in evolving site architectures requires continuous alignment between observed usage patterns, anticipated growth trajectories, and external constraints that vary by region and regulation, and the approaches that integrate automated tools with structured review processes have produced measurable improvements in stability across multiple documented cases. As new telemetry standards emerge in September 2026 and beyond, organizations that maintain flexible mapping practices stand to adapt more readily to the shifting demands these environments present.